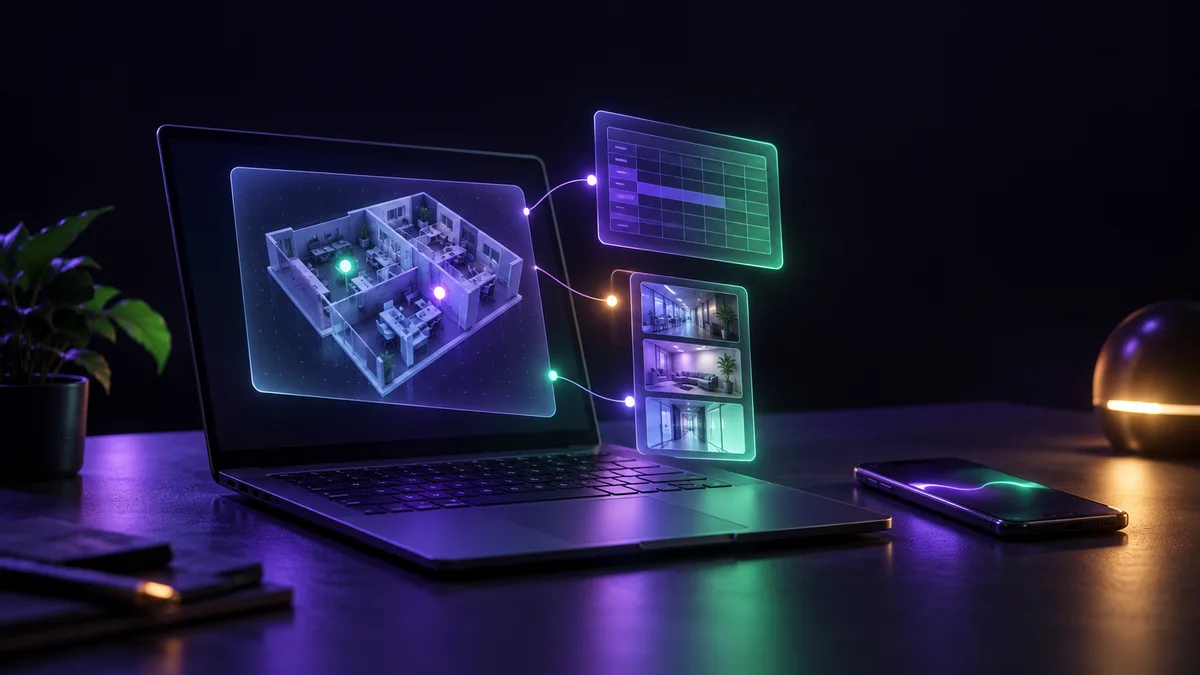
Ask an AI agent to drive Blender and place access points in a 3D model. That is one scene from a demo PC Watch's Shimizu built around a sales situation; in his scenario, the salesperson's request, in Japanese, is "make it two APs" 1.
The other case: after a livestream, vertical video previews are made automatically, and the creator sends back fix instructions to finish them. PC Watch's Wakasugi built a system of his own that automatically makes vertical videos for YouTube Shorts after a livestream 2 3.
Shimizu bought his ASUS ProArt P16, while Wakasugi used a ProArt P16 loaned by NVIDIA 4 2. The interesting part is how each of them split what to do locally from what to leave to cloud AI.
120万円払ってRTX Sparkノートを買った。で、AIエージェントで元は取れる? https://t.co/NGEejs1A2g #RTXSpark pic.twitter.com/tloJ2dsu8r
— PC Watch (@pc_watch) October 26, 2026
Shimizu: a hypothetical sales demo
Shimizu bought the 128GB configuration of the ProArt P16 as the next main PC for his home 4. The headline of the PC Watch feature says, roughly, "I paid for an RTX Spark laptop. Can AI agents pay it back?" 5
What follows is a demo imagined for a sales situation, not results from a real customer visit.
- In his scenario, Hermes drives Blender through MCP and places access points in a 3D model [[F285]]
- Hermes can use Windows Search through PowerShell to find documents in a local folder [[F313]]
- Hermes can change values in Excel from PowerShell via COM, then run a macro that numbers items automatically and exports a quote as a PDF [[F314]]
But not everything ran on the laptop. Shimizu writes that he used the cloud service ChatGPT Work for some steps: creating the office 3D model, the code for skills and the code for Blender 6. His reason is that handing everything to Hermes and a local LLM takes too long. It is not impossible, he adds, but he is describing the Hermes and Qwen3.8-27B setup he used, kept at its default settings 7.
He gives speeds as well. With Qwen3.8-27B and similar models, output tops out at about 15 tokens/s, and the first token takes around 6 seconds with reasoning on and about 0.9 seconds without 8. For speed he personally recommends Qwen3.6-35B-A3B, and says that without at least 50 tokens/s it gets very stressful 9.
He states the split in his own words. For shortening the whole workflow and improving quality, complex processing and anything that can be prepared in advance is better done with ChatGPT or Claude 10. Simple external-app control, file search and routine Excel operations, on the other hand, suit local execution 11.
Wakasugi: development on the main PC, hands-on editing on the loaner
Wakasugi's clip automation separates where it is built from where it runs. He instructed that development happen on his main PC and the hands-on video editing be done with the RTX Spark machine, and chose to use the Qwen3.8-27B already installed on the RTX Spark as the local LLM 12. The headline of his column for PC Watch says, roughly, that local AI on RTX Spark creates clip videos automatically, and that the system took only 3 days to build 13.
【配信修行僧】RTX SparkでローカルAIが切り抜き動画を自動作成、たった3日で作ったシステムの中身 https://t.co/NkrrLBc8AM pic.twitter.com/cp7enP8gMm
— PC Watch (@pc_watch) October 22, 2026
- Design: with the standard Hermes and Qwen3.8-27B setup he often found even chat slow, and wanting to develop quickly, he designed the features with Claude in the cloud, on a separate PC [[F321]]
- Transcription: ffmpeg extracts the audio from the video and whisper.cpp transcribes the whole thing [[F322]]
- Laughter and smile cues: he added sherpa-onnx for audio and MediaPipe for video [[F323]]
- Topic splitting and scoring: Hermes on RTX Spark (with a local LLM) divides the transcript by topic and scores how entertaining each segment is every 45 to 70 seconds [[F324]]
- Picking clips: it selects 3 to 5 segments scoring 7 or higher and turns them into videos [[F325]]
- Fixes: instructions go through a Telegram bot, and can be sent from a phone too [[F326]]
One more point matters: Hermes does not do the work each time. Routine steps are run by task-specific Python code that Claude wrote, and Hermes steps in only when needed as the go-between for the author and each piece of code 14. Splitting topics and scoring them is still done by the local LLM under Hermes on RTX Spark, as above 15. Wakasugi himself writes that, if he wanted, this feature could be done without Hermes, and that Hermes was in a sense forced into the workflow 16.
The timings are concrete. Reaching 4 previews took about 30 minutes: about 6 minutes for transcription and topic splitting, about 6 to 7 minutes for choosing highlights, and about 3 minutes per preview 17. After revisions, the final export takes about 5 minutes per video 18.
His sense is that roughly 7 in 10 of what the AI produced could be used as is, and he sent fix instructions for the remaining 3 in 10 19. The system was done in 3 days, and he writes that he wrote not a single line of code himself 20. He also notes that Telegram conversations bloated the log, and a single message sometimes meant re-reading a huge chunk of log and waiting about 3 minutes 21. He dealt with it by having a plugin written that keeps tool output out of the conversation and starts a fresh conversation for each reply 22.
How each of them split it
Shimizu says complex processing and anything that can be prepared in advance is better done with the cloud ChatGPT or Claude 10, and that simple operations, file search and routine Excel work suit the laptop 11. Wakasugi splits it into development on the main PC with Claude in the cloud and the hands-on video editing with the RTX Spark machine 23 12.
Different scenes and different writers, yet both leave the building and preparing to cloud AI and mostly use the RTX Spark laptop to run prepared steps. In Wakasugi's case, though, the local LLM handles splitting topics and scoring them 15. He also calls the way Hermes was worked in "forced" 16.
So is a high-priced machine worth buying? Shimizu's conclusion is that for now the uses are still limited, and it is closer to an experiment 24. Personally, he writes, if you want practical returns at this stage, paying for existing cloud services instead is also an option 25. His honest impression is that one more generation of progress is needed before the pieces fit together 26. Take that as material for your own decision.
Video generation comes with a wait
@Ai_Quse posted a record of generating MiniMax H3 video on a Surface Laptop Ultra.
Surface Laptop Ultra レポートVol.3💻
— きゅうす のAIとつれづれ (@Ai_Quse) October 26, 2026
ついにノートPCで動画生成!
RTX SparkのVRAM割当は、NVIDIAアプリから最大95.5GBまで設定できました。
MiniMax H3で1920×1088・10秒の動画を生成。完成まで76分。
時間はかかるけど、このサイズの動画をノートPCで作れるのは凄い!
Qwen3.8… pic.twitter.com/pWYD9HDTi1
According to the post, the VRAM allocation for RTX Spark could be set up to 95.5GB from the NVIDIA app 27. The creator writes (in Japanese) that a 1920×1088, 10-second video from MiniMax H3 took 76 minutes to finish 28.
Power draw was about 90 to 100W for both Qwen3.8 4bit and the H3 video generation, the creator says 29. The fans ran almost flat out, but the creator writes that GPU temperature stayed steady at about 70°C during 60 minutes of continuous generation 30. @Ai_Quse notes that this is a record from their own setup 31.
Before you buy: Arm snags and model limits
The articles by Shimizu and Wakasugi also describe snags specific to Arm, plus a limit of this particular model 4 2.
- The Arm build of Blender 5.2 LTS has no CUDA support, so the renderer cannot select the GPU [[F294]]. Shimizu put GPU use first and used the x64 build [[F295]]
- A dependency of the Blender MCP server (cryptography) was unavailable for ARM64, so he set up an x64 Python environment [[F296]]
- OBS runs, but native Windows on Arm support is still treated as under verification, and scripts and hardware encoders are not supported (Wakasugi) [[F333]]
- The ProArt P16 has an NPU but is not a Copilot+ PC, and Studio Effect, Recall and the Photos app's super resolution are unavailable [[F318]]
Mobile01 likewise strongly advises that anyone using specific professional software, external devices or development tools check native support and behavior before buying 32. Check the official compatibility information for the tools you want to run before you buy.
If you plan to keep video material on hand for a pipeline like the clip system, you will want somewhere to store it.
You can also look for RTX Spark laptops on Amazon.
Ad: the “Search on Amazon” buttons are affiliate links, and we may earn a commission. They open a search, not a specific listing.
Ad: the “Search on Amazon” buttons are affiliate links, and we may earn a commission. They open a search, not a specific listing.
Read next
If memory capacity is your sticking point, see how reviewers' measurements compare RTX Spark memory options. For handing 3D work to an agent, there is driving Blender with an AI agent; for mass-producing video locally, the local video factory.